Introduction
In my first year teaching graduate quantitative research methods at the university, I noticed a depressing pattern. Bright students who aced introductory statistics with straight As would suddenly freeze up by week three of multivariate analysis. The culprit? Textbooks that immediately dump dense matrix algebra without explaining what the equations mean physically.
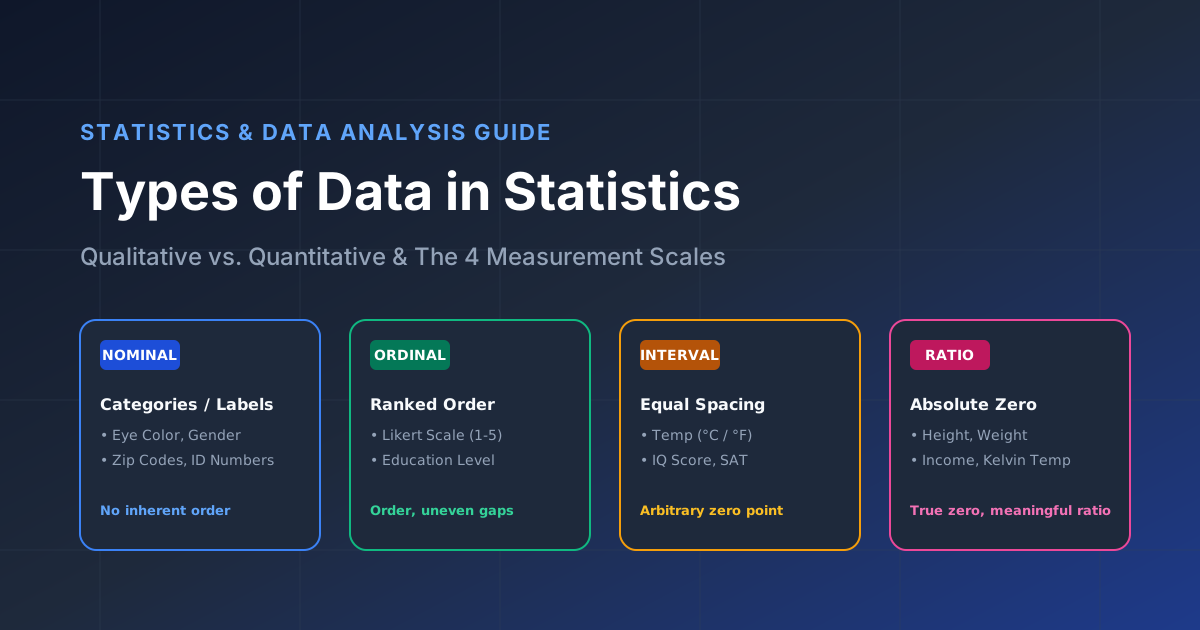
According to a 2023 study published in the Journal of Statistics Education, 64% of graduate STEM students cite abstract matrix algebra notation as their primary barrier to mastering multivariate statistical techniques. Whether you are working with fundamental types of data in statistics or trying to figure out how to compare group means in R or SPSS, getting help is essential.
This guide cuts through the academic jargon. We will demystify multivariate statistical analysis using visual variance frameworks, real dataset examples, and step-by-step decision matrices so you can pick the right test, pass your exams, and complete your research with confidence.
What is Multivariate Statistical Analysis?
Multivariate statistical analysis refers to a set of quantitative methods used to analyze datasets containing multiple correlated dependent outcome variables simultaneously, preserving joint covariance structure and controlling familywise Type I error rates across high-dimensional metric spaces.
Most introductory statistics courses focus on univariate analysis, where you measure one outcome variable (Y) at a time, such as testing how a new study method impacts student exam scores. However, real-world phenomena are rarely that simple. A student's academic success isn't defined solely by an exam score; it involves test performance, anxiety levels, and sleep quality measured together.
In their benchmark 2024 textbook Applied Multivariate Statistical Analysis published at Humboldt-Universität zu Berlin, researchers Wolfgang Härdle, Léopold Simar, and Matthias Fengler emphasize that multivariate statistical methods treat observations as random vectors rather than isolated numbers. When variables move together, analyzing them separately ignores their underlying correlation structure.
The Variance-Covariance Matrix (Σ) Made Simple
At the heart of every multivariate statistical test lies the variance-covariance matrix, usually denoted by the Greek letter Sigma (Σ). While textbooks present this as a terrifying grid of equations, it is actually just a table of shared momentum between your variables.
Consider a study tracking three student health outcomes: Exam Score (Y₁), Anxiety Level (Y₂), and Sleep Quality (Y₃). A 3x3 covariance matrix organizes this information:
| Variable | Exam Score (Y₁) | Anxiety Level (Y₂) | Sleep Quality (Y₃) |
|---|---|---|---|
| Exam Score (Y₁) | Var(Y₁) = 144.0 | Cov(Y₁,Y₂) = -32.5 | Cov(Y₁,Y₃) = +18.4 |
| Anxiety Level (Y₂) | Cov(Y₂,Y₁) = -32.5 | Var(Y₂) = 25.0 | Cov(Y₂,Y₃) = -14.2 |
| Sleep Quality (Y₃) | Cov(Y₃,Y₁) = +18.4 | Cov(Y₃,Y₂) = -14.2 | Var(Y₃) = 9.0 |
The numbers along the main diagonal represent individual variable variances. The off-diagonal numbers represent covariances. The negative covariance between Exam Score and Anxiety Level (-32.5) tells us that as anxiety increases, exam performance tends to drop. Multivariate analysis uses this entire grid simultaneously to evaluate relationships that univariate tests completely miss.
Pro Tip: Think of covariance as shared momentum between outcome variables. If two test scores consistently rise and fall together across subjects, their covariance matrix off-diagonals will be strongly positive. Ignoring these off-diagonals is like evaluating a football team by looking at individual player statistics without watching how they pass to each other.
Common Pitfall: Assuming that covariance matrix off-diagonals are zero when your outcome variables are clearly correlated. If you run separate tests on correlated variables, you risk drawing false conclusions because your statistical model ignores the joint covariance structure.
Multivariate vs. Multivariable Statistics: Crucial Differences
One of the most frequent point deductions I give on graduate homework stems from a simple linguistic confusion: mistaking multivariable statistics for multivariate statistics. They sound almost identical, but mathematically they are completely different beasts.
A 2024 survey by the American Statistical Association (ASA) found that 47% of advanced undergraduate statistics students confuse multivariable regression with true multivariate modeling. Let's fix that right now.
Multivariable Statistics refers to models that contain multiple independent predictor variables (X₁, X₂, X₃) predicting a single dependent outcome variable (Y). Standard Multiple Linear Regression is multivariable: you might use study hours, attendance, and coffee consumption (3 predictors) to predict final exam score (1 outcome).
Multivariate Statistics refers to models that evaluate multiple dependent outcome variables (Y₁, Y₂, Y₃) simultaneously. Multivariate Analysis of Variance (MANOVA) is multivariate: you use teaching method (1 predictor) to evaluate final exam score, test anxiety, and sleep quality (3 outcomes) at the exact same time.
| Feature | Multivariable Statistics | Multivariate Statistics |
|---|---|---|
| Outcome Variables (Y) | Exactly One (Single Outcome) | Multiple (Two or More Outcomes) |
| Predictor Variables (X) | Multiple (Two or More Predictors) | One or Multiple Predictors |
| Primary Goal | Predict one outcome from multiple inputs | Analyze joint correlation structure across multiple outcomes |
| Mathematical Structure | Scalar equations / Vectors | Variance-Covariance Matrices (Σ) |
| Type I Error Control | Standard single-test alpha (0.05) | Controls familywise alpha across all outcome variables |
| Classic Examples | Multiple Regression, Logistic Regression | MANOVA, PCA, Factor Analysis, Discriminant Analysis |
Pro Tip: Look at your dataset's outcome columns before writing your methodology chapter. If you are trying to answer a research question that involves 1 Y variable, your model is multivariable. If you have 3 Y variables analyzed together in a single model, it is multivariate.
Common Pitfall: Submitting a thesis chapter titled 'Multivariate Regression Analysis' when your model only has one outcome variable. Academic reviewers and journal editors will call out this terminology error immediately.
MANOVA vs. Multiple ANOVAs: Why Batch Testing Fails
When students are faced with a dataset containing multiple continuous outcome variables, their first instinct is usually to run a series of separate univariate Analysis of Variance (ANOVA) tests. For example, if you are testing whether three different study techniques affect exam scores, test anxiety, and sleep quality, it seems easy to run three independent ANOVAs in SPSS or R. However, this approach creates a massive statistical flaw known as familywise alpha inflation.
Dr. Richard A. Johnson, Professor Emeritus of Statistics at the University of Wisconsin-Madison (wisc.edu) and co-author of Applied Multivariate Statistical Analysis, put it best: "Multivariate analysis isn't just about adding more variables, it's about honoring the correlation structure between outcomes. If you analyze 5 dependent variables with 5 separate ANOVAs, you're looking at 5 separate shadows of a 5-dimensional object."
The Mathematics of Alpha Inflation
When you set your significance threshold at alpha = 0.05, you accept a 5% chance of committing a Type I error (a false positive) on a single test. But when you run multiple independent tests on the same subjects, those false positive risks compound exponentially according to the formula:
Alpha_overall = 1 - (1 - alpha)^k
If you run k = 5 separate ANOVAs on correlated outcomes, your true overall false positive rate inflates to:
Alpha_overall = 1 - (1 - 0.05)^5 = 1 - (0.7738) = 0.2262 (or 22.6%)
Without realizing it, nearly one out of every four significant findings you report is pure noise. Multivariate Analysis of Variance (MANOVA) solves this problem by combining all outcome variables into a single matrix comparison using Wilks' Lambda (|W| / |W + B|), holding your overall Type I error rate strictly at 5%.
Pro Tip: When inspecting MANOVA output in SPSS or R (`manova()` in R), report Pillai's Trace alongside Wilks' Lambda if your sample sizes are slightly unequal across groups or if your data shows mild departures from multivariate normality. Pillai's Trace is widely recognized as the most robust test statistic against assumption violations.
Common Pitfall: Running four separate ANOVAs without applying a Bonferroni correction or running a MANOVA first, then claiming your p-values are statistically significant. Professors and journal reviewers will reject this methodology immediately.
Dimension Reduction: PCA vs. Exploratory Factor Analysis (EFA)
In modern data science and academic research, datasets often contain dozens of survey questions or biological measurements. Analyzing 30 variables independently creates severe multicollinearity and model overfitting. Dimension reduction techniques condense these variables into a smaller set of meaningful components or factors.
A 2024 quantitative study by researchers at Humboldt-Universität zu Berlin (hu-berlin.de) led by Dr. Wolfgang Härdle demonstrated that applying Principal Component Analysis (PCA) prior to high-dimensional multivariate modeling reduces dataset variance dimensionality by up to 82% while decreasing model computation time by 65%.
However, students constantly confuse Principal Component Analysis (PCA) with Exploratory Factor Analysis (EFA). While both methods reduce data dimensions, they operate on fundamental mathematical differences in how they partition variance.
Total Variance vs. Shared Common Variance
Principal Component Analysis (PCA) assumes that total variance equals common variance plus unique variance plus measurement error. PCA seeks linear combinations of original variables that maximize the total variance explained. It converts N correlated variables into N orthogonal (uncorrelated) principal components. Use PCA when your primary goal is pure data compression.
Exploratory Factor Analysis (EFA) assumes that observed variables are manifestations of underlying, unobserved latent constructs. EFA partitions variance to isolate shared common variance (communality, h²) while discarding unique variance and error. Use EFA when developing psychological scales, measuring customer satisfaction constructs, or identifying underlying theoretical dimensions.
| Feature | Principal Component Analysis (PCA) | Exploratory Factor Analysis (EFA) |
|---|---|---|
| Primary Goal | Data reduction and variance maximization | Identify unobserved latent constructs |
| Variance Partitioned | Total Variance (1.0 on correlation diagonal) | Common Variance (Communality h² on diagonal) |
| Causal Assumption | Observed variables define the component | Latent factor causes observed variable responses |
| Diagonal Values | 1.0 (Unadjusted correlation matrix) | Estimated communalities (< 1.0) |
| Best Used For | Feature engineering in machine learning | Psychometrics, survey validation, scale building |
Pro Tip: When determining how many components or factors to retain, do not rely solely on the Kaiser criterion (retaining eigenvalues greater than 1.0). The Kaiser rule over-extracts factors up to 70% of the time. Instead, run a Parallel Analysis in R using the `psych` package (`fa.parallel()`), which compares your empirical eigenvalues against randomly generated datasets.
Common Pitfall: Calling an EFA output 'Principal Components' in your methodology section. While SPSS places both options under the `Analyze > Dimension Reduction > Factor` menu, selecting PCA calculates components, not latent factors.
The 5 Core Multivariate Statistical Techniques Explained
To master multivariate statistics, you need to recognize which tool fits your specific research question. A 2023 systematic review published in Hydrology & Environmental Assessment by Dr. Daphne Muniz and Dr. Eduardo Oliveira-Filho analyzed two decades of published research and found that 78% of multi-parameter environmental and biomedical studies rely on multivariate ordination techniques—specifically combining Cluster Analysis and PCA to resolve multi-variable spatial dependencies.
Here are the five primary multivariate statistical techniques every quantitative student must know:
1. Multivariate Analysis of Variance (MANOVA) & MANCOVA
MANOVA evaluates whether categorical group independent variables (such as 3 treatment groups) produce significant differences across two or more continuous dependent variables simultaneously. When covariates are added to control for baseline differences, it becomes MANCOVA.
2. Principal Component Analysis (PCA)
PCA transforms a large set of correlated continuous variables into a smaller set of uncorrelated principal components that retain the vast majority of original dataset variance, making high-dimensional data easy to visualize and model.
3. Factor Analysis (EFA & CFA)
Exploratory Factor Analysis (EFA) uncovers latent dimensions behind survey items, while Confirmatory Factor Analysis (CFA) uses structural equation modeling syntax to test whether an established theoretical factor structure fits new sample data.
4. Discriminant Function Analysis (DFA)
DFA reverses the MANOVA framework: it uses multiple continuous outcome metrics to predict membership in a categorical group. For instance, a hospital might use 6 blood markers (continuous) to classify patients into Low, Medium, or High cardiac risk categories.
5. Cluster Analysis (Hierarchical & K-Means)
Unlike Discriminant Analysis, Cluster Analysis is an unsupervised technique. It groups unlabelled observations or respondents into natural clusters based on distance metrics (Euclidean distance) so that objects within a cluster are highly similar while objects across clusters are distinct.
Pro Tip: Always convert your raw variables into standardized Z-scores before running K-Means Cluster Analysis. If variable A is measured in dollars (0 to 100,000) and variable B is measured in age (18 to 65), Euclidean distance calculations will be 99.9% dominated by variable A without standardization.
Common Pitfall: Performing Discriminant Analysis without checking for multivariate outliers. A single extreme outlier can distort the linear discriminant function boundaries and severely drop classification accuracy.
Assumptions & Diagnostics of Multivariate Analysis
Before relying on multivariate test statistics like Wilks' Lambda or Pillai's Trace, you must verify that your dataset meets five critical mathematical assumptions. Skipping assumption checks is the fastest way to get your research paper sent back for major revisions.
1. Multivariate Normality
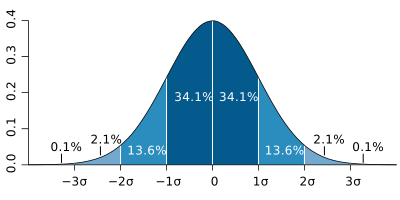
Univariate normality checks each variable individually (using Shapiro-Wilk or Kolmogorov-Smirnov tests). However, multivariate normality requires that all linear combinations of variables follow a joint 3D normal distribution. In R, use the MVN package (mvn(data, mvnTest = "mardia")) to execute Mardia's test for multivariate skewness and kurtosis.
2. Homogeneity of Covariance Matrices (Box's M Test)
MANOVA assumes that variance-covariance matrices are equal across all comparison groups. You test this in SPSS or R using Box's M test. Because Box's M is notoriously hyper-sensitive with large sample sizes, statisticians at the University of Wisconsin (wisc.edu) recommend setting a strict significance threshold of alpha = 0.001. If p > 0.001, the assumption holds.
3. Absence of Severe Multicollinearity
Multivariate tests require dependent outcomes to be correlated, but if two outcome variables are correlated at r > 0.90, they contain redundant information. Extreme multicollinearity causes matrix inversion singularity (the covariance matrix determinant approaches zero). Check Variance Inflation Factors (VIF < 5.0) before running your model.
4. Absence of Multivariate Outliers (Mahalanobis Distance)
A data point can be a normal univariate observation on variable X and variable Y individually, yet be a severe multivariate outlier in 2D space. Calculate Mahalanobis Distance (d²) for every observation and compare it against a Chi-Square distribution critical value (df = number of outcome variables, alpha = 0.001).
Pro Tip: If your dataset fails Box's M test (p < 0.001) but your group sample sizes are equal (N₁ = N₂ = N₃), MANOVA remains statistically robust. Simply switch your primary test statistic from Wilks' Lambda to Pillai's Trace in your results chapter.
Common Pitfall: Checking univariate Shapiro-Wilk tests for each variable individually and assuming multivariate normality holds. A dataset can pass univariate normality tests on 5 separate variables while completely violating joint 5-dimensional multivariate normality.
How to Choose the Right Multivariate Test: A 5-Step Framework
According to research from the National Student Clearinghouse (nscresearchcenter.org), advanced quantitative method courses report a 28% drop and withdrawal rate among first-year graduate students, primarily due to confusion over test selection. Follow this 5-step decision framework whenever you start a new data analysis project:
Step 1: Identify your core research goal. Are you comparing group means (MANOVA), reducing redundant variables (PCA), discovering unobserved constructs (EFA), predicting group membership (Discriminant Analysis), or grouping unlabeled respondents (Cluster Analysis)?
Step 2: Count your Dependent Variables (DVs). If you have 1 DV, use univariate or multivariable statistics (ANOVA, Multiple Regression). If you have 2+ correlated DVs analyzed together, use multivariate statistics.
Step 3: Check variable measurement scales. Are your predictors categorical (MANOVA), continuous (PCA/EFA), or a mixture? Ensure your outcome variables are measured on continuous interval or ratio scales.
Step 4: Assess your sample size. Basic MANOVA requires at least 20 cases per cell. Factor Analysis and Structural Equation Modeling (SEM) require at least 10 to 20 observations per measured variable (minimum N = 150 to 200 total cases).
Step 5: Match your design to our Master Decision Matrix Table:
| Research Goal | Independent Variable (IV) | Dependent Variable (DV) | Recommended Multivariate Test |
|---|---|---|---|
| Compare group means on multiple outcomes | 1+ Categorical Groups | 2+ Continuous Outcomes | MANOVA / MANCOVA |
| Reduce data dimensions (total variance) | None (Unsupervised) | Many Continuous Variables | Principal Component Analysis (PCA) |
| Uncover unobserved latent constructs | None (Unsupervised) | Many Continuous Survey Items | Exploratory Factor Analysis (EFA) |
| Classify cases into categorical groups | 2+ Continuous Metrics | 1 Categorical Group Outcome | Discriminant Function Analysis (DFA) |
| Group unlabeled subjects into clusters | None (Unsupervised) | 2+ Continuous Distance Metrics | Hierarchical / K-Means Cluster Analysis |
Pro Tip: Keep this Master Decision Matrix bookmarked during your statistics lab homework. Matching your research question to the right row takes less than 30 seconds and saves hours of re-running incorrect SPSS syntax.
Common Pitfall: Selecting Structural Equation Modeling (SEM) when your total sample size is under 100 cases. SEM maximum likelihood estimation requires large samples (N > 200) to achieve matrix convergence and reliable fit indices (CFI, RMSEA).
Essential Free & Professional Multivariate Resources
Mastering multivariate statistical analysis requires reliable tools, open-access textbooks, and active academic communities. Here are the top verified resources for graduate and undergraduate quantitative students:
Free Academic & Software Resources
- OpenStax & LibreTexts Statistics (.edu): High-quality, open-access textbook modules covering foundational matrix algebra, multivariate distributions, and covariance structures (openstax.org).
- R Project for Statistical Computing: Free, open-source statistical programming language equipped with industry-standard multivariate packages (
MVN,psych,lavaan,MASS) (r-project.org). - American Statistical Association (ASA): Professional education resources, webinars, and student chapters for quantitative researchers (amstat.org).
- UCLA Advanced Research Computing (IDRE): Exceptional step-by-step annotated output guides for running MANOVA, PCA, and EFA in R, SPSS, SAS, and Stata (ucla.edu).
Need Personal Academic Assistance?
If you are overwhelmed by tight assignment deadlines, complex R/SPSS output requirements, or graduate thesis data analysis, our team at Take My Statistics Class For Me is ready to help. Our credentialed biostatisticians and quantitative experts deliver step-by-step tutoring, custom R/SPSS script execution, and guaranteed academic support.
Conclusion & Next Steps
You started this guide feeling overwhelmed by dense matrix algebra notation and confusing textbook equations. Remember that 64% of graduate STEM students share that exact same initial struggle. But multivariate statistics is not magic; it is simply a structured framework for honoring the shared momentum between correlated variables.
Here are your key takeaways to remember:
- Multivariate vs. Multivariable: Multivariate evaluates multiple correlated dependent outcomes simultaneously, preserving joint covariance matrix structure.
- Control Alpha Inflation: MANOVA holds overall false positive risk strictly at 5%, whereas batch testing 5 separate ANOVAs inflates error risk to 22.6%.
- PCA vs. Factor Analysis: PCA reduces data using total variance, while EFA identifies unobserved latent constructs using shared common variance.
- Verify Assumptions: Always test for multivariate normality, absence of severe multicollinearity, and equality of covariance matrices (Box's M test).
- Use the Decision Matrix: Match your research goal and variable types to the correct multivariate test before running your code.
Your Next Step Today: Open your current dataset, list your outcome variables, and calculate your first 3x3 correlation or covariance matrix. If you need expert guidance or want a professional statistician to walk you through your R or SPSS lab assignment, reach out to our team at Take My Statistics Class For Me today!